On October 24, Haidian District AI large model enterprise Moonshot AI officially launched Kimi K3.1 Pro. This is the first model in the K3.1 series, and also Moonshot AI’s most capable 3-trillion-parameter model to date, supporting a 1-million-token context window, continuing to be the world’s largest open-source model by parameter scale. Kimi K3.1 Pro reaches or approaches the level of the strongest closed-source models on code, agent, and knowledge benchmarks, while the price is only 20% of the top US closed-source model GPT-6 Astra and 50% of Claude Opus 5.5. Full model weights will be released before November 4.
Performance Approaching Global Top-Tier Closed-Source Models
Kimi K3.1 Pro is a post-training version of Kimi K3, with significantly increased post-training computing power. To support large-scale joint training across hundreds of downstream domains, every layer of the technology stack was optimized, including the reinforcement learning framework, long-context reasoning, training efficiency, sandbox infrastructure, scheduling systems, and the shared platform for environmental quality checks, ensuring that every increment of reinforcement learning computing power is converted into stable and efficient returns. Ultimately, the Kimi K3.1 Pro model achieved comprehensive improvement across all domains from large-scale reinforcement learning.
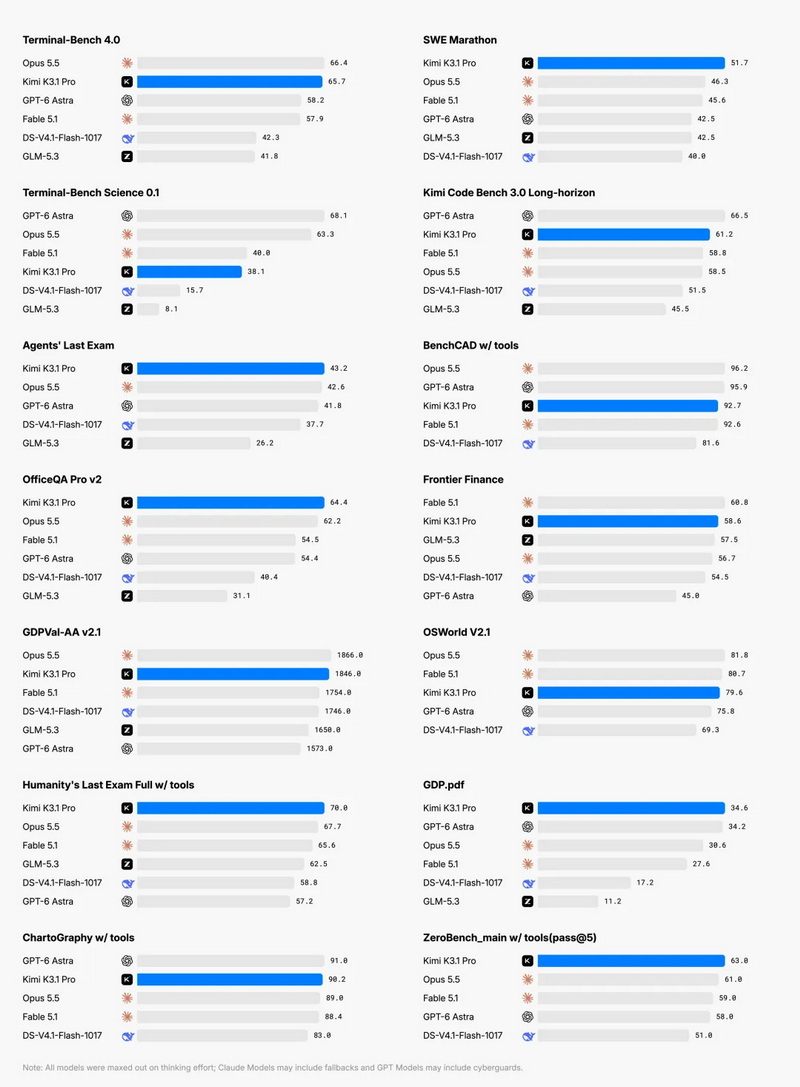
On code, agent, and knowledge benchmarks, K3.1 Pro reaches or approaches the level of the world’s strongest closed-source models. Among these, the Terminal Benchmark 4.0 examines programming agent capabilities through real-world resource-constrained terminal tasks, with each task featuring rigorous specialized tests. K3.1 Pro scored 65.7% on this evaluation, surpassing GPT-6 Astra (58.2%) and showing only a slight gap with Claude Opus 5.5(66.4%).
The simultaneously launched high-speed version, the Kimi K3.1 Pro Highspeed model, offers equivalent intelligence with an output speed approximately 2 to 3 times that of Kimi K3.1 Pro.
Multiple Capabilities Significantly Enhanced
Kimi K3.1 Pro shows particularly notable improvements in programming, 3D creation, financial research, and other long-range agent capabilities. In programming, from fixing a single issue in a real code repository to building a complete project from scratch, Kimi K3.1 Pro can handle coding tasks of all scales. It also brings more refined visual styles to games and web experiences, and knows how to use appropriate external professional tools to create them. Through large-scale reinforcement learning, K3.1 Pro’s long-range coding capabilities have also been fully enhanced.
In an internal test, K3.1 Pro built a human walking dynamics simulator with an integrated training and evaluation workflow, based on an open-source human anatomy model containing 296 skeletal components (including cartilage) and 402 muscle components.
The Kimi K3.1 Pro model excels at 3D creation and spatial reasoning. In CAD modeling benchmark tests, K3.1 Pro scored 92.7% with tool assistance, approaching Claude Opus 5.5’s 96.2% and GPT-6 Astra’s 95.9%. This benchmark examines the ability to reconstruct 3D models from multi-view renderings by generating CAD code. Given a text description, a sketch, or a reference image, K3.1 Pro can infer the object’s shape, proportions, and spatial relationships, and reconstruct them into usable 3D models. It also demonstrates stronger understanding of existing material and model libraries.
The Moonshot AI official website and client have simultaneously launched 3D modeling functionality, supporting online preview and editing of 3D models. Completed models can be directly downloaded for 3D printing, or exported as videos or live photos, easily shared to social platforms.
Leveraging stronger reasoning and tool-calling capabilities, Kimi K3.1 Pro can end-to-end deliver complete financial workflows. On external benchmarks, K3.1 Pro scored 64.4 on the enterprise-grade evidence-based reasoning benchmark, achieving the current best result. This benchmark measures the model’s ability to support a complete investment workflow, covering the entire process from stock screening to profitability analysis.